How an AI Agent Factory Pipeline Builds TheCalculatorHive
15 min read
TheCalculatorHive is a calculator site — compound interest, EMI schedules, Black-Scholes option pricing, income tax, BMI.
I don't write the calculators.
I don't write their specifications either.
A pipeline of AI agents researches each formula, verifies it independently, writes the spec, writes the tests before the engine exists, builds the module, drives the page in a browser hunting for defects, and opens a pull request.
This was an experiment. It was the first time I tested how far AI could go at building a real product — not writing functions faster, but taking something from nothing to production over about six weekends. Most of what I learned came from being wrong about which parts would be hard.
One example before the architecture. A tax calculator shipped with a wrong effective rate after passing every check I had built: research, independent verification, tests written before the code, thirteen CI gates. All green, and all wrong in the same direction. The last section is why.
The pipeline
The definition phase comes first. Nothing gets written until the maths is settled:
Then the build phase:
And finally, routing by risk:
One constraint produced all of this. These pages work out someone's tax, their loan repayments, their retirement figures. A wrong number here isn't a rendering bug that a user reports — it's a wrong answer about money, published under my name and quietly believed. So everything follows from one rule: the maths has to be established before any code is written, and recorded somewhere I can audit later.
The agents
Splitting the work across separate agents is what lets a later stage disagree with an earlier one. A single agent checking its own work just agrees with itself.
| Agent | Does | Gate |
|---|---|---|
opportunity-scout | Finds candidates from search demand and public sitemaps | seeds backlog |
formula-researcher | Sources the formula, variables, units, assumptions | writes research record |
formula-verifier | Re-derives independently, dimensional analysis, hand-computed examples | confidence + conflict flag |
spec-author | Assembles and validates the spec | hard |
test-author | Writes the suite before the engine exists | tests-first |
calculator-builder | Engine, module, page | hard |
ui-qa-reviewer | Drives the live page: recalc, labels, structured data, 375px | hard |
edge-case-reviewer | Adversarial inputs — NaN, overflow, blank results | hard |
seo-reviewer | Content, metadata, structured data | scored |
competitor-comparison | Gap analysis against top results | soft |
self-improvement | Post-launch passes over live pages | cadence |
The researcher works down a ranked hierarchy of sources, where official and academic publications outrank general reference sites. It needs three independent sources that agree, and at least one of them has to be authoritative.
The verifier then re-derives the formula from scratch, and is explicitly told not to trust the researcher's arithmetic. It checks that the units balance on both sides of the equation — dimensional analysis, where a mismatch is an automatic failure rather than a deduction. It hand-computes worked examples, probes the boundaries, and raises a conflict flag if two authoritative sources genuinely disagree. That flag sends the calculator to a human no matter how confident everything else looks.
One clarification on opportunity-scout: it reads competitors' public sitemaps for topic discovery only, to find which calculators exist that I don't have. No content or formula comes from them, and those domains are blocked from ever appearing as a citation.
Duplicates are killed before any research is spent, in three layers. The first catches a slug collision, which is the obvious case. The second compares functional signatures — the keywords, inputs, outputs and formula — to spot the same calculator arriving under a different name.
The third layer catches what the other two miss. It rewrites each spec's formula into an equation structure, replacing every variable name with a placeholder while leaving the numeric constants alone. Two calculators doing identical maths under different names collapse to the same structure, and a formula that is a strict subset of another scores as a full match. Renaming the variables doesn't hide the algebra.
Building one calculator, end to end
| # | Step | Command or agent |
|---|---|---|
| 1 | Reserve the slug under a lock | factory:select --reserve |
| 2 | Research the formula from ranked sources | formula-researcher |
| 3 | Re-derive independently, check units, hand-compute examples | formula-verifier |
| 4 | Author and validate the spec | spec-author → factory:validate |
| 5 | Scaffold the module skeleton | factory:scaffold |
| 6 | Write tests from the spec — expected to fail | test-author |
| 7 | Fill the engine maths until tests pass | calculator-builder |
| 8 | Hard gates | npm test, tsc, factory:conformance, factory:verify-all |
| 9 | Regenerate derived files | factory:generate |
| 10 | Browser review, functional and adversarial at 375px | ui-qa-reviewer, edge-case-reviewer |
| 11 | PR → CI → merge | factory:open-pr |
Step 9 is where the calculator actually joins the site. Regenerating produces its registry entry, its search record, its slot in the API route map, its build-time seed, its published sources and its sitemap date. There is no manual registration step anywhere.
The commands
| Command | Use |
|---|---|
/factory-run [count] [category] | Batch run from the backlog |
/factory-run --parallel --slugs roi,inflation | Build specific named calculators |
/factory-run --parallel 5 finance --window 10 | Concurrent lanes, one PR |
/factory-run --unattended [count] [category] | Never asks, never pauses |
Underneath, all of this is plain Node scripts, so the same checks run locally, in CI, and inside worktrees — the separate checkouts that each parallel build gets to itself. Three commands carry most of the design:
npm run factory:scaffold -- specs/<slug>/spec.json
npm run verify
npm run factory:resume -- <runId>factory:scaffold writes the entire module skeleton for you: types, reducer bounds, schema, URL state, compute, panels, article, an engine stub and the page. All of it type-checks and passes the conformance gate immediately, as stubs. Only two things get filled in afterwards — the engine maths and the article prose.
verify runs the whole local gate chain in order: generated-file drift, typecheck, the full test suite, catalogue wiring, architecture lint, spec-corpus validation, pipeline-state validation.
factory:resume is crash recovery, which I'll come to below.
The entry point itself is just a markdown file. Putting factory-run.md in .claude/commands/ is what puts /factory-run in the menu, and that file is deliberately a nine-line pointer whose whole job is to say read the skill and follow it exactly:
The instruction lives in exactly one place, and everything else points at it. The command file has barely changed since I wrote it, while the skill behind it has more than tripled in size.
I had assumed that written instructions were safe from the kind of rot that affects code. They aren't. An earlier command did inline its build steps rather than reference them, and when the architecture changed underneath, it quietly decayed into instructions that produce work the CI gates now reject.
The spec, and who writes it
Everything downstream is built from the spec, so it matters a great deal where its contents come from. By the time spec-author runs, two records already exist:
research.json holds the formula, every variable and its unit, the assumptions, the limitations, the sources with quoted passages, and a proposed risk tier.
verification.json holds the second agent's independent work: hand-computed examples, edge cases, the dimensional analysis, a confidence score and the conflict flag.
How those two get merged matters more than the assembly itself:
- Worked examples come from the verifier, who re-derived them without ever seeing the researcher's arithmetic. They become the spec's
examples[], and later the test assertions — so a published worked example cannot drift away from the engine. - Only authoritative sources get labelled for publication. A competitor page used as a numerical target stays in the record as research and never reaches the page.
- The risk tier is floored by category, whatever the researcher proposed.
- The conflict flag is carried through. An unresolved disagreement between sources forces a human review, regardless of confidence.
The spec has 27 required fields, trimmed here to the ones that matter:
{
  "slug": "emi",
  "riskTier": "high",
  "scope": "universal",
  "timeSensitive": false,
  "seed": { "module": "loans/emi", "compute": "computeEmiResults" },
  "inputs":  [{ "name": "principal", "min": 0, "max": 1e9, "default": 1000000, "clamp": true }],
  "outputs": [{ "name": "emi", "label": "Monthly EMI", "format": "currency" }],
  "formula": {
    "expression": "EMI = P·r·(1+r)^n / ((1+r)^n − 1); r = annual%/12/100",
    "assumptions": ["Fixed rate over the term", "Reducing-balance interest"],
    "limitations": ["Excludes processing fees and insurance"]
  },
  "sources":  [{ "url": "…", "kind": "official", "quote": "…" }],
  "examples": [{ "inputs": {}, "expectedOutputs": {}, "precision": 2 }],
  "lifecycle": { "version": 1, "status": "live", "lastValidatedAt": "…" }
}The validator enforces rules that go beyond checking the shape of the file:
| Rule | Enforcement | Why it exists |
|---|---|---|
| Risk floor | Finance, loans and health must be high risk | Auto-approval is low-risk-only, so a mis-tiered money calculator could ship unreviewed |
| Time sensitivity | Forces the build-time seed off; a separate check reads the code to confirm the declaration is honest | An age calculator is otherwise permanently convinced it's the day it was built |
| Scope | Universal, or bound to a country with a badge and pinned currency | Mill-rate property tax and money-factor leasing shipped "universal" with a currency switcher; neither exists outside the US |
| Source policy | Competitor domains blocked from published citations | A competitor tells you what number users expect, never what's correct |
This is what "AI-generated" actually means here. Not that a model wrote some code, but that a model produced a structured, machine-validated artifact describing what to build and why it's correct — and everything else is derived from that artifact mechanically. What I contributed is the schema, the merge rules and the validator: the constraints on what a spec is allowed to say, rather than the content itself.
The architecture
The whole system follows one rule: write a fact down once, and generate everything that needs it from that single copy.
The spec is that single copy. From it come the registry, the search index, the API route map, the icons, the build-time seeds, the published sources and the sitemap dates — and I never touch any of them directly.
That's the point: once the rule is explicit, CI can enforce it. On every push it rebuilds all those files from the specs, holds the result in memory, and compares it against what's committed. If anything differs, the build fails. Edit a generated file by hand and your change simply won't merge, so the spec and the site can't drift apart.
Further down, in the code, the same idea shows up as a shared runtime contract. A calculator module doesn't implement its own input handling, URL state or accessibility — the contract owns all of that, because those are exactly the parts that are easy to get subtly wrong:
| Concern | Owned by |
|---|---|
| Debounced recalculation, request cancellation | CalculatorShell — latest input always wins |
| Instant first paint | Build-time seed — no "Calculating…" flash |
| Shareable URLs | makeUrlState — each field decoded independently, so a partial link never collapses to defaults |
| Input bounds | createClampedReducer(bounds) — the bounds table is the reducer |
| Validation | One schema.ts, shared by the edge route and URL parsing |
| Accessibility | Shared components — one debounced screen-reader summary |
| The maths | A pure engine, React-free, never shipped to the browser |
What's left for each calculator is data wiring plus its own maths, and nothing else. An architecture linter holds that line: the build fails if a module writes its own rate limiting, inlines a clamp rather than calling the shared one, declares a second validation schema, or pulls a maths engine into code the browser can reach.
The same habit turns up in the small details too. The breadcrumbs you see on the page and the BreadcrumbList in the structured data come out of one function, so they can't drift apart. Every worked example in an article is produced by the engine that computes the result on screen, so the two can never disagree.
Neither of those is clever. They just make it impossible for two copies of the same fact to contradict each other.
Parallel builds
I assumed throughput was limited by the machine. When I actually measured a run, the machine sat mostly idle — the bottleneck was the shape of my own workflow. The first design used wave barriers, where every calculator in a batch had to finish before the next batch started, so each run kept collapsing down to a single lane waiting on its slowest member.
Each calculator now builds in its own worktree with its own dev server, so the browser-driven review agents can drive real pages without colliding. Merges still have to be serialised, because they touch generated files, but they overlap with the builds that are still running — a finished calculator integrates while the others carry on. That sliding pool of lanes, rather than more hardware, is where the throughput came from.
One more rule came out of a disaster: the snapshot happens before review, not after.
A run once destroyed every build that hadn't yet merged. "Awaiting human review" wasn't a value in the outcome enum, so it was recorded as a failure — and the failure path force-removed the worktree that held the only copy of the work.
The fix wasn't better error handling. It was adding the missing state, then committing every build to a git ref the moment it passes its hard gates. Cleanup now refuses to run, with its own exit code, whenever removing a worktree would drop the last reference to work that has already passed.
If a run is killed, factory:resume reconciles from git rather than from a manifest. A merge commit means that calculator is done; a snapshot without one means the merge needs replaying; neither means it has to be rebuilt.
Unattended runs
--unattended is for when nobody is at the keyboard. The contract is never block, never pause, never ask, and four rules make that safe:
- Park, don't pause. A calculator that needs a human is marked
awaiting-review— a state, not a failure — and the loop moves on. This is the same distinction that caused the data loss above. - Stage only. Nothing is committed or pushed. An unattended process with push rights has a much larger blast radius than one without.
- Keep the tree green. A build that can't be fixed in one corrective pass has its own files reverted, so it can't poison the gates for everything built after it.
- Self-refill. If the backlog empties,
opportunity-scoutruns and the loop carries on.
The output is a returning-queue ledger: one row per calculator, with its outcome, risk tier, confidence and the path to its review packet. Unattended runs produce reviewable work, not published work. You start a run and come back to an open pull request with a preview deployment, never to calculators that have put themselves live.
What does make them live is merging. Availability is simply code presence — a built calculator is live on its branch's preview deployment, where it can actually be used, and live in production once that branch merges. Approval became a non-blocking stamp that drives the "last reviewed" date on the page, and takedown is a request-time override in middleware.
My first attempt was a real gate, and it deadlocked. "Not live" meant the route 404'd in every environment, including the preview — so reviewing a calculator required making it live, and making it live required having reviewed it.
The CI gate chain
Thirteen checks run on every push and pull request, and they divide into two kinds that catch very different things.
The first kind reads the code:
- Generated-file drift — regenerate everything from the specs, fail on any difference
- Typecheck, the full test suite, catalogue wiring, architecture lint, spec-corpus validation
The second kind waits for a production build, then reads what actually ships:
- Structured data parsed out of the rendered HTML, not the source
- First-load JavaScript measured against a budget
- A real browser at 375px, asserting no horizontal overflow
- Metadata length budgets, as a hard failure
The second kind catches more real defects, which surprised me. Linting tells you the code looks right; parsing the HTML a browser will actually receive tells you the page is right. Those turn out to be different claims more often than I expected.
Every defect becomes a mechanical rule
When something breaks, fixing it is only half the work. The other half is working out what class of defect it belonged to, and adding something mechanical that stops the whole class. There are forty of these:
| Rule | Enforcement | Origin |
|---|---|---|
| Unit toggles round-trip losslessly | A test that discovers unit toggles by scanning the filesystem — a new one needs a suite or a documented exemption | Feet→cm→feet lost the user's entered value |
| Never define a React component inside a component | Architecture lint rule | A calculator shipped with untypeable inputs — the nested component remounted on every keystroke, dropping focus |
| Chart labels stay inside their viewBox | Bounding-box test per gauge | A label drew below the visible area and was silently cropped — SVG clips internally, so page-overflow checks are blind |
| No two calculators share a formula | Identifier-blind structural comparison | Two calculators shipped identical maths under different names |
Each architecture rule has a deliberately broken fixture committed alongside it, and a test that fails if the rule ever stops firing. A guard that dies quietly is worse than no guard at all, because you carry on trusting it.
Two honest limits, though. The habit misfires sometimes: I once wrote a careful guard for a cookie banner and deleted the banner the next day. And one class of defect stays out of reach entirely — the cropped SVG label, a theme animation that landed in the wrong corner only on Android because the coordinates are scaled by device pixel ratio, a dark-mode date picker whose browser-drawn icon came out black on black. Every one of those was found by a person looking at a real screen.
Where the human stays
The deepest wrong assumption was the one the whole pipeline rested on: that enough layered checks add up to correctness.
A tax calculator shipped dividing by the wrong income figure. It passed research, independent verification, tests written before the code, the check that recomputes documented examples against the real engine, and every CI gate. It passed all of them because all of those artifacts came from the same model family carrying the same misconception. They agreed with each other, and they were wrong in the same direction.
Separating the work doesn't separate the assumptions. Different agents, different files, one forbidden from reading the other's arithmetic — none of it helps when the misunderstanding underneath is shared. What helps is something that can disagree from outside the system:
| Oracle | Example | Availability |
|---|---|---|
| Published third-party figure | A reference price a vendor publishes for known inputs | Rare |
| Mathematical invariant | Put-call parity; lossless unit round-trips | Domain-dependent |
| Domain-literate human | The tax bug | Always; doesn't scale |
That calculator had neither of the first two, so nothing in the system could contradict it. Which is why money, health and loans always go to a person, and why the agents are forbidden from recording a review decision themselves.
It's the question I now ask before building anything: what could disagree with this? If the only thing checking the work is the thing that produced it, that's consensus, not verification.
The result
The Black-Scholes calculator shows the full chain most clearly, because option pricing has both of the things most calculators lack: a published reference value, and an invariant that has to hold no matter how the code is written.
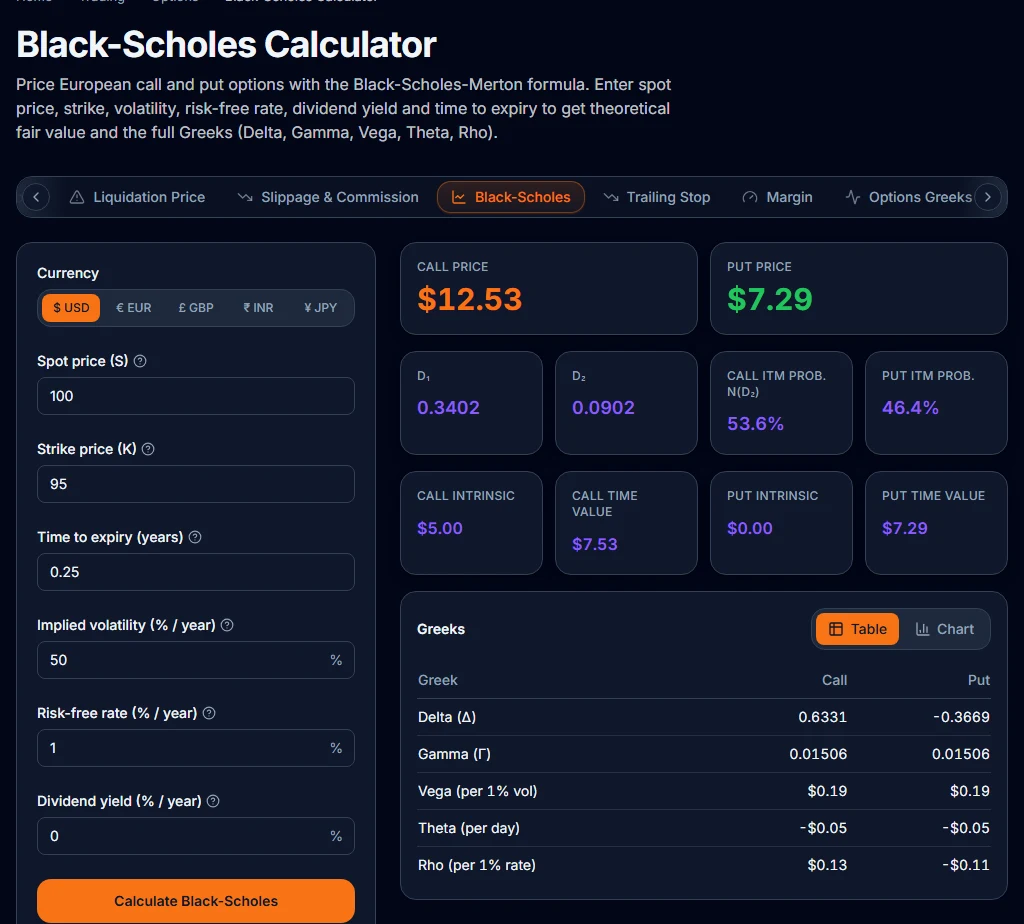
That figure started as a number someone else published. It was re-derived by hand independently, entered the spec as a worked example, became a test assertion, was implemented, cleared CI and deployed — and you can check it against the original source without ever seeing my code.
It's also the most favourable case in the catalogue, and worth saying so. Most calculators have no published reference and no invariant to check against. Plenty finished with a conflict flag because two authoritative sources disagreed on a convention, and those rest on a choice I made and documented rather than on settled fact. Which is precisely why the money, health and loan calculators still cross a human desk.
Two things to take from this. Make the target precise rather than the prompt — a prompt is written once and lost, while a specification can be validated and rejected by CI. And order the pipeline so that nothing grades its own work.